[1] - https://nitter.netbub.com/AlexKrentsel/status/21173766837246...
There are a lot of known neurons in the older Qwen models that are long known to induce behaviour changes (see evil Qwen by changing one weight).
My question boils down to how much is trained vs being able to actually understand the weights. Presumably a same gen model isn’t trained on any sources dissecting that generation. And how much do longer known conceits like steering vectors, J spaces, LoRAs play into this?
This doesn’t explain the game training cases, which are very impressive to me.
That sounds a bit like biology; maybe AI will become like that.
Some poor-ass professor -- fighting tooth and nail for tenure, or at least some form of stability from all-powerful admin staff -- can't keep themselves from trying to figure out who's "Dominant" or "Alpha". When in reality the network isn't directed, but a mesh of arbitrary weights, vectors, and dimensionality.
Perhaps if ancient China had beat us to Enlightenment and Industrial Revolution we would be seeing scientists talking about how respectful mammals are of their ancestors.
I think your use case of incorporating novel data probably calls for training, but I'm sure there are use cases where you can tweak the weights to get what you want (say I wanted to tweak the model to be less sycophantic, or found a way to shrink it by removing weights associated with a language that I don't ever use)
Essentially, my training introduced knowledge and structure which wasn't translating into results. I tried training in a few different ways, different ranks, different things, and I wasn't making any progress.
With weight editing, a larger model was able to eliminate some undesirable pathways which the model was often using. Without going into the nitty-gritty, it basically took my best LoRa checkpoint and gave it the skills that I was unable to get with further training.
You can optimize a model by randomly changing its weights and validating results on your task. A monkey can type a book given enough attempts.
For training you would need to hook it up to a LoRA training harness, identify the looping weight direction, and adjust the weights accordingly. I've not (yet) looked into how to do this.

My first reaction to your question (rhetorical?) was uncharitable... so, I am curious what you meant that it was "easy."
The age of source code is definitely not going to end anytime soon if ever. But the future will involve incomprehensible machines editing other models in a "fairly certain" way, but we are going to need a lot of tooling to keep up with the process and not just take the model updates as "trust me bro".
So i asked Qwen 3.8 27B two things:
1. What it is this network all about? I only gave it the ann.c code that implemented a simple artificial neural network library in C and the setup code that specified the network's shape but not its purpose.
Qwen 3.8 27B tried a bunch of stuff, taking the layers one by one, proding numbers through it, etc and finally figured out it is some sort of 5x5 to 2x2 filter, most likely working with pixels (i never mentioned pixels or graphics), though it wasn't certain about the exact purpose. It did rule out a bunch of uses like being a downscaler or classifier, from its behavior.
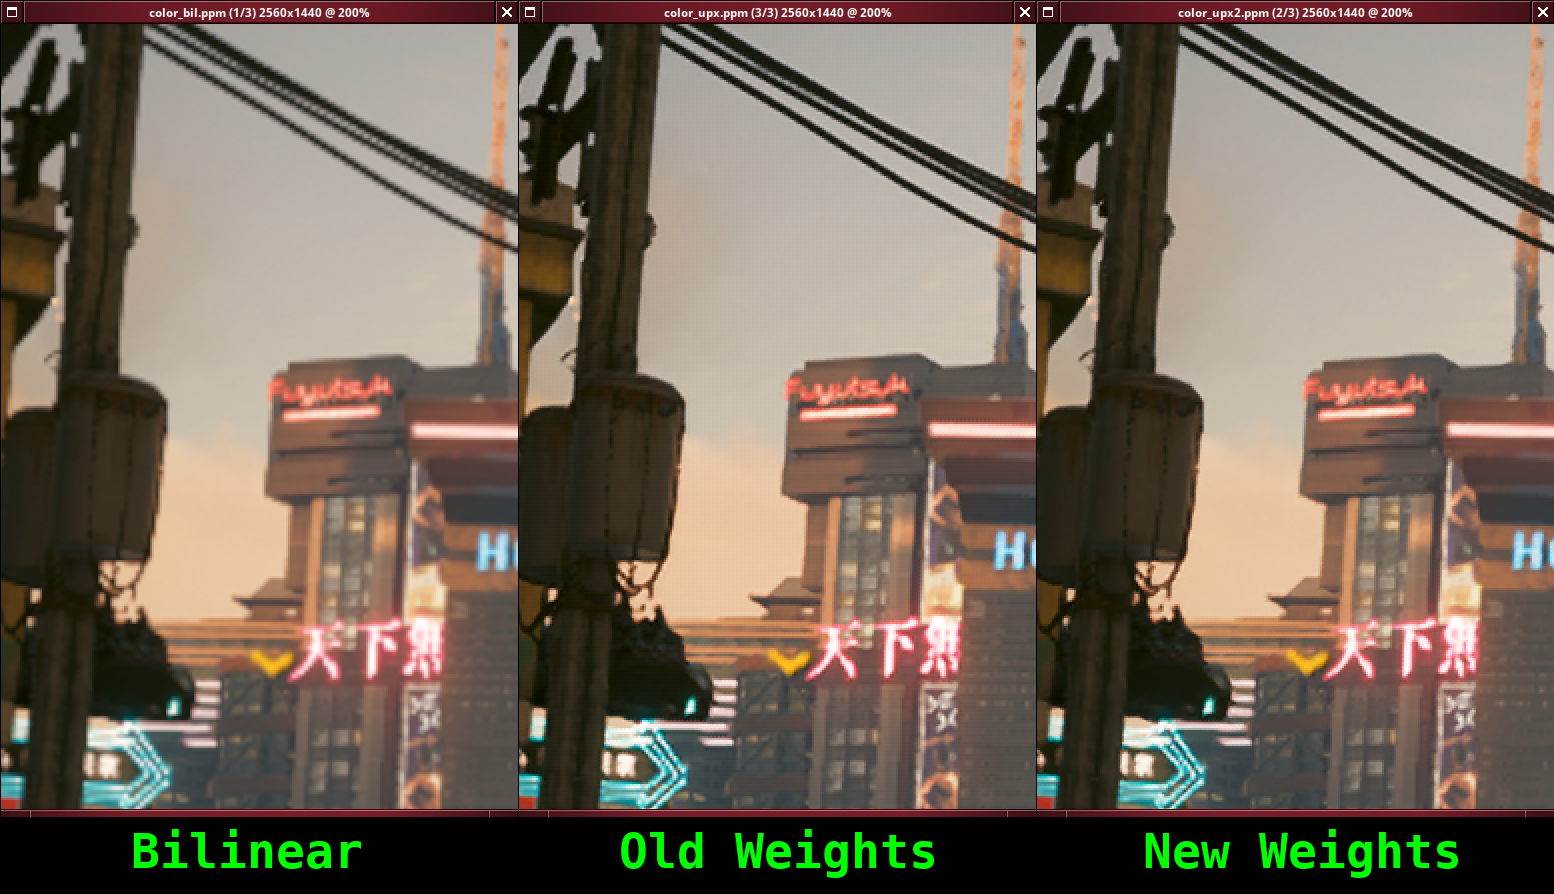
2. After i revealed what it was, i asked it if it can improve it but keep it 100% compatible with the existing program that used the weights file. And sure enough, it did improve it. I gave it the original training C code and dataset. It made a few experiments (and wrote its own training C code because it found mine too slow :-P) and ended up improving the weights. The difference[1] is small, but it basically eliminated some small noise that was always there and made some transitions less "halo-y". Of course for the purpose i wanted it (use it to upscale games in realtime) it isn't that great (too heavy) but it was learning material anyway. Though one bonus thing i noticed is that it upscales my random doodles much better than any Krita filter[2] :-P.
The above isn't Qwen 3.8 27B observing the weights directly and making sense out of them (ok actually it did seem to make some sense of the weights in the "#1" but i didn't dump the entire network to it - though thinking about it, it is only around 16384 floats so it might work). It just used a bunch of scripts it wrote in Python (and later C) but i still found it interesting to watch it go at it.
[0] https://mastodon.gamedev.place/@badsector/113765818432603610
[1] http://runtimeterror.com/pages/iv/images/a3d94ea369ff95ecf05...
[2] http://runtimeterror.com/pages/iv/images/4e29d027a8aa6e89db5...
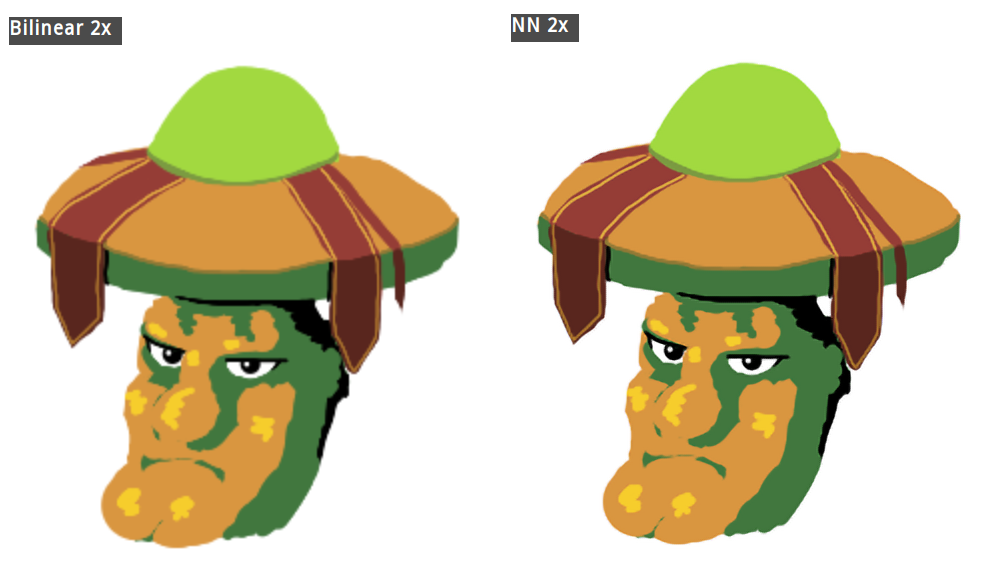
> the 2x2 pixel grid that the input pixel should be replaced for a (width2)x(height2) upscale.
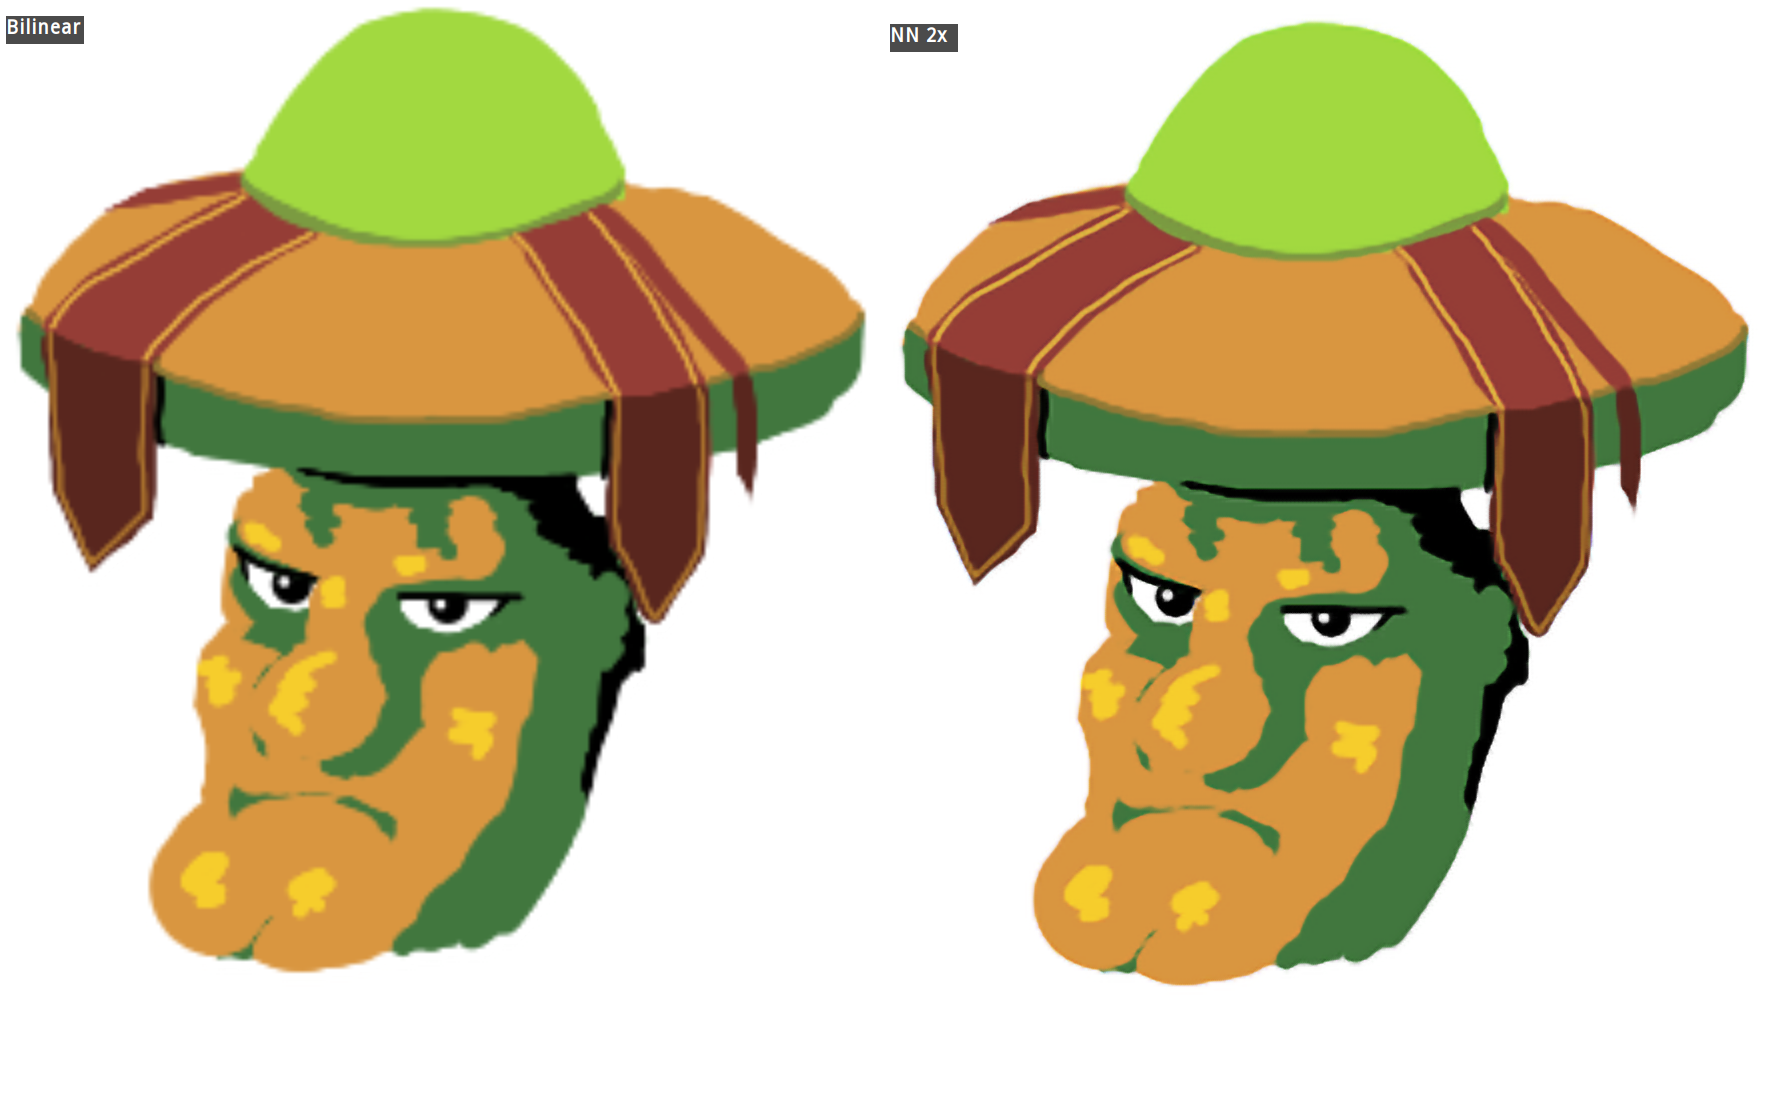
Out of curiosity i did apply it twice to the drawing i posted in my previous comment with a 4x bilinear upscale made in Krita[1]. TBH i think a dedicated 4x network would do a better job though even then, there is only so much a network can hallucinate to fill in details :-P.
[0] https://github.com/badsectoracula/gamescope/tree/neural-netw...
[1] http://runtimeterror.com/pages/iv/images/20b9558400bcf26511d...
It's a blog post which received feedback from collaborators.
It hasn't gone through the academic paper lifecycle ... the authors themselves refer to it as a post and as preliminary.
I feel like I'm taking crazy pills, but can we be precise when talking about work of this form? It started with referring to arXiv pre-prints as papers, and now we're at blog posts with an academic template as papers.
A paper is a fucking paper: something which has been vetted by the scientific community, with at least some form (often, a few rounds) of anonymous review from people outside your circle of collaborators
This is not there yet, and clearly so due to the various feedback from people (including the two pushback posts on HN) critiquing the lack of discussion about the existence of these techniques in mech interp, etc?
I called it a paper here because it's by people with an academic affiliation and is of comparable quality (if not better than) many of the other "papers" we see.
I also like it when a paper isn't a PDF. PDFs are a bad way of communicating information.
(I will note that the authors themselves didn't call it a paper, their own BibTeX reference calls it a "blog post":)
  @misc{takehi2026weightspace,
    title        = {{Sparks of Weight-Space Programming: LLMs can natively read \& write neural network weights}},
    author       = {Takehi, Rikiya and Teoh, Jayden and Zhang, Alex and Khattab, Omar},
    year         = {2026},
    month        = nov,
    howpublished = {\url{https://rikiyat.github.io/blog/weight-space-programming/}},
    note         = {Blog post}
}They have the strength of one PDF being frozen & (mostly) treated online as immutable - compared to a webpage which might change, or a blog post which might be edited. If a PDF needs to be replaced there'll be a notice.
And the single-file nature of PDFs makes them more likely to sit in an archive not managed by the author (vs a blog) so they tend to live as long as the archive rather than the author's blog.
For something that needs to Be referenced by others those are useful properties - I'd argue they outweigh how good PDF is at communicating information.
But for (1, 2), just to point out, neither of your criteria would pass muster in the scientific communities who are ultimately responsible for vetting this work, right?
The ideal is: we don't accept papers at NeurIPS (or wherever) because of affiliation, and the badge of "quality" is bestowed by peer review, from other scientists.
> is of comparable quality (if not better than)
But the posts that you refer to in your own post point out several ways in which the quality is not good ...
But, in any case, I find it a bizarre choice to call it a paper when the authors themselves do not refer to it as such. We can agree to disagree, but just offering feedback.
I admit that I don't think formal "papers" deserve their elevated status in today's information economy.
I think they add a whole lot of ceremony that usually results in a format that's harder to understand.
So me calling this a "paper" was a little bit of a dig!
You, being of sound mind, tried the technique and drew reasonable conclusions … but just look at the original post for this blog post: there are a large number of responses by people who clearly don’t understand the technique, missed the experimental weaknesses, couldn’t place the post into the lineage of mech interp results that preceded it … and will leave the discussion with the wrong impression.
In your mind, whose fault is that? Is that that the unavoidable cost of a field, moving too rapidly to engage in peer review?
In its ideal form, the paper lifecycle is not a gate, but a sharpening stone.
I'm not convinced the alternative - delaying publication by 6 months, keeping the new information available only to a much smaller group until then - would have been better.
All of that said, I did just update my own post to include "The paper (OK, the authors classify is as a “blog post”, but it’s paper-shaped) found that frontier models..." inspired by this conversation.
From memory, yolo and roberta and ppo were initially rejected. After a quick google search, pagerank was initially rejected, word2vec got one weak and one strong reject in reviews, LSTM got rejected (90s but still), dropout, knowledge distillation, and many more such cases. All of these are extremely important, foundational and field defining papers that ended up on arxiv or other preprint places.
If that happened to those papers, there's 0 chance today that it'd be a good idea. The field is simply moving too fast, there's too much being published, and the "top venues" are simply swamped. Blog / preprint / carrier pigeon is ok atm, as long as someone can look at it, try it, and hopefully reproduce it.
GLENDOWE: I can call spirits from the vasty deep.
HOTSPUR: Why, so can I, or so can any man, but will they come when you do call for them?
I can interpret weights too, but will that interpretation be correct?
Chances are much higher than a model can figure out what the patterns are, decipher them, and retain that knowledge in a meaningful way it can reason about. Me and you might take years or months to do all of that on our own, with a "map" of the weight we might be able to discuss it, but not as effortlessly as an LLM.
Honestly, I had told a few different colleagues that reading a model is probably not that exclusive to frontier models. It's probably yet another reason OpenAI / Anthropic don't release any big open weight models, but thankfully Google and Microsoft release reasonably sized models. Imagine a new GPT open weight release, it would get dissected drastically.
Why do this without testing? Why would you assume that?
Isn't that what this whole technology paradigm is about? How is it surprising?
Granted, it is cool. But I see so much of "look at this cool thing I did with LLMs" and honestly... we need more structured text, more explicit documentation, more ergonomic and intuitive CRUD applications.
The amount of "look at cool things" is growing way faster than before and they are all sort of low effort now because the "agentic" LLM-VM looping apparatus can do a lot of heavy lifting and run with our prompts.
And I mean, if one has jargon, knowledge, and intention, they can also leverage that into great structured text, ergonomic and intuitive CRUD apps etc, all of which add great value to our mundane pursuits of applied research, software products and services and so on.
Honestly, I begin to think the problem is people dazzling themselves instead of doing the housekeeping that is the bulk of life. Technology choice is entirely secondary.
No, not at all. I recommend you learn some of the basic linear algebra about how these things work before engaging in wild and completely nonsensical speculation.
Are you sure you have read and understood his point?
It seem quite possible that the flattened-model-weights ingested into a model have a much greater fidelity of representation in a similar model's KV cache than they do in a human's working memory, and that being able to loop and digest and chunk makes it unsurprising that models can excel at this type of task.
I think that's the point the person is making. Do you disagree? If so, why?